A narrated scene has two jobs: make the words understandable and give them a setting. If the music competes with a name or a closing sentence, a more impressive soundtrack can make the piece less useful.
Suno introduced Speech beta on October 1, 2026, describing speech and its soundtrack generated together, with availability on web and mobile. That is the feature announcement; the production choices below are our editorial workflow, not results from an audio benchmark. Sources were checked on October 8.
Start with the part you cannot change
For a fictional audio scene, delivery and music can develop together. For an approved product explanation, the exact wording may matter more than a spontaneous performance. Choose the workflow around that constraint.
| Project | A useful starting approach | Decide before generating |
|---|---|---|
| Original spoken vignette | Explore speech and music together | Which sentence carries the scene? |
| Podcast opening sketch | Test a short spoken identity with a restrained bed | Where does the host enter? |
| Approved narration with names or numbers | Record or prepare narration separately, then fit BGM | Which words must remain exact? |
| Video with fixed edit points | Keep narration and music independently editable | Which picture changes require a pause? |
These are production recommendations, not a claim that Speech cannot handle a particular use. Separate tracks simply make it easier to change one layer without replacing the other. For that approach, use our instrumental BGM workflow.
Write a small brief before trying a whole episode
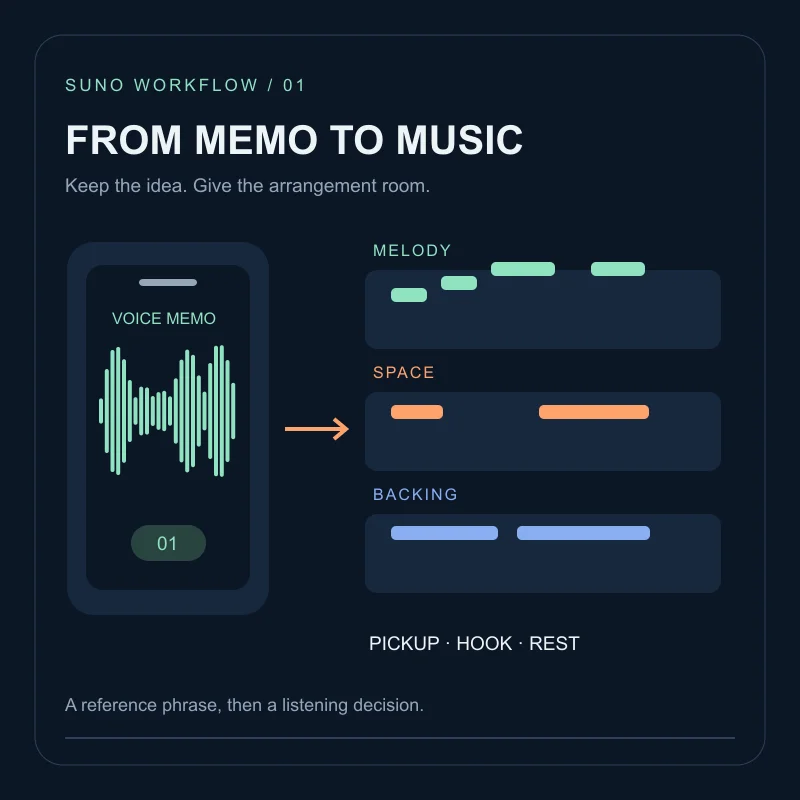
Use three parts: the text, the way it should be spoken, and the role of the music. Avoid asking for a cinematic climax if the important information arrives in the final sentence.
Here is an original practice brief. Its length is intentionally small so you can compare every word; it is not a tested preset or a promise of exact timing.
Text:
The station clock has stopped. A bicycle waits by the gate.
I leave the key beneath the blue cup and take the long way home.

Delivery:
Quiet conversational narration. Leave a short pause after the first sentence.
Keep the last phrase calm rather than dramatic.

Music:
Sparse felt piano and a low sustained texture.
Keep the music behind the voice. No sung hook or busy percussion.
Follow the current Speech interface when entering the brief. The release note links an official video walkthrough; it does not document a stable set of text fields, exact duration limits or plan pricing. Do not assume a musical prompt field is a dedicated Speech script field.
Review the words before the atmosphere
First, listen while reading the script. Mark substitutions, missing words and awkward stress. Second, close the script and listen for intelligibility. Third, listen only to the entrance, pauses and ending. A cue can sound attractive in isolation and still interrupt the meaning of a sentence.
Use a short log rather than a general score:
Take A: final phrase masked by piano; wording correct.
Next test: remove piano movement during the last sentence.
Keep: text and delivery instructions.
Take B: [write what you actually hear]
If the wording changes, simplify the text before adding more emotional directions. If the words are right but difficult to hear, simplify the music request. If timing must match a fixed video and several attempts still miss it, move to separate narration and BGM rather than spending the whole session rewriting adjectives.
Define a stopping point
For a draft, accept a take only when the wording is correct, the key sentence is understandable without reading, and the ending leaves room for the next scene. Save rejected takes with a reason; do not describe them as proof that the model always behaves that way.
Speech remains labelled beta in the October announcement. Recheck its interface before a client delivery, and use the publishing checklist for source records and the final exported file. Speech generation does not, by itself, establish consent to imitate a real person’s voice.
FAQ
Is Speech the same as adding spoken-word cues to a song prompt?+
The October announcement describes a dedicated Speech beta model. Spoken-word wording in a music prompt is an instruction, not evidence that the Speech model is selected.
Does this workflow guarantee an exact script or duration?+
No. Compare the generated words and timing with your brief. Keep narration separate when precise revision control is essential.
When should narration and music stay separate?+
Keep them independently editable when the script contains fixed names or numbers, narration has already been approved, or pauses must match an existing video edit.